
Natural Language Processing (NLP) is experiencing significant growth, and the life sciences industry is increasingly adopting this groundbreaking technology. As a subfield of linguistics, computer science, and artificial intelligence (AI), NLP focuses on the interaction between computers and human language. Specifically, it involves programming computers to process and analyze large volumes of natural language data.
This enables computers to classify a document, and then extract valuable information and insights, categorize data, and organize it for further use. Within life sciences, these capabilities have particular value in pharma, where organizations work with large volumes of complex, highly regulated documentation.
What is pharma NLP?
Pharma NLP is the use of natural language processing to read, classify, and extract information from the text that drug developers and manufacturers produce and receive, such as research literature, clinical trial documents, and safety reports. It is one branch of AI in pharma, alongside the machine learning methods used in drug development.
The pharma and life sciences applications covered in this article are:
- Answering biomedical research questions from published studies
- Building biomedical knowledge graphs that connect findings across research data
- Classifying and migrating clinical trial documents to the trial master file (TMF)
- Detecting and reporting adverse drug events (ADEs) for pharmacovigilance
NLP models, content moderation, and applications in life sciences
Depending on the intended application, organizations can choose from different NLP models and approaches to process, analyze, and interpret language. There are licensed, open-source, and Software-as-a-Service (SaaS) NLP models today, which each offer different advantages and limitations.
In 2020, Facebook AI (now Meta AI) launched M2M-100, the first AI model capable of translating between 100 languages without relying on English as an intermediary. M2M-100 was trained on 2,200 language directions, or 10 times more than earlier English-centric multilingual models. The solution was also more scalable and customizable.
Other examples of NLP include DALL-E, a popular platform that creates AI-generated images based on text information. GitHub, meanwhile, made GitHub Copilot generally available in June 2022, an AI tool that suggests code automatically as developers write.
In the life sciences, open-source NLP resources include PubMedQA. PubMedQA is a dataset of biomedical research questions, each answered with yes, no, or maybe based on a PubMed abstract. It is used to train and evaluate NLP models for medical question answering.
Examples of PubMedQA questions include:
- Do spontaneous electrocardiogram alterations predict ventricular fibrillation in Brugada syndrome?
- Do liver grafts from selected older donors have significantly more ischaemia reperfusion injury?
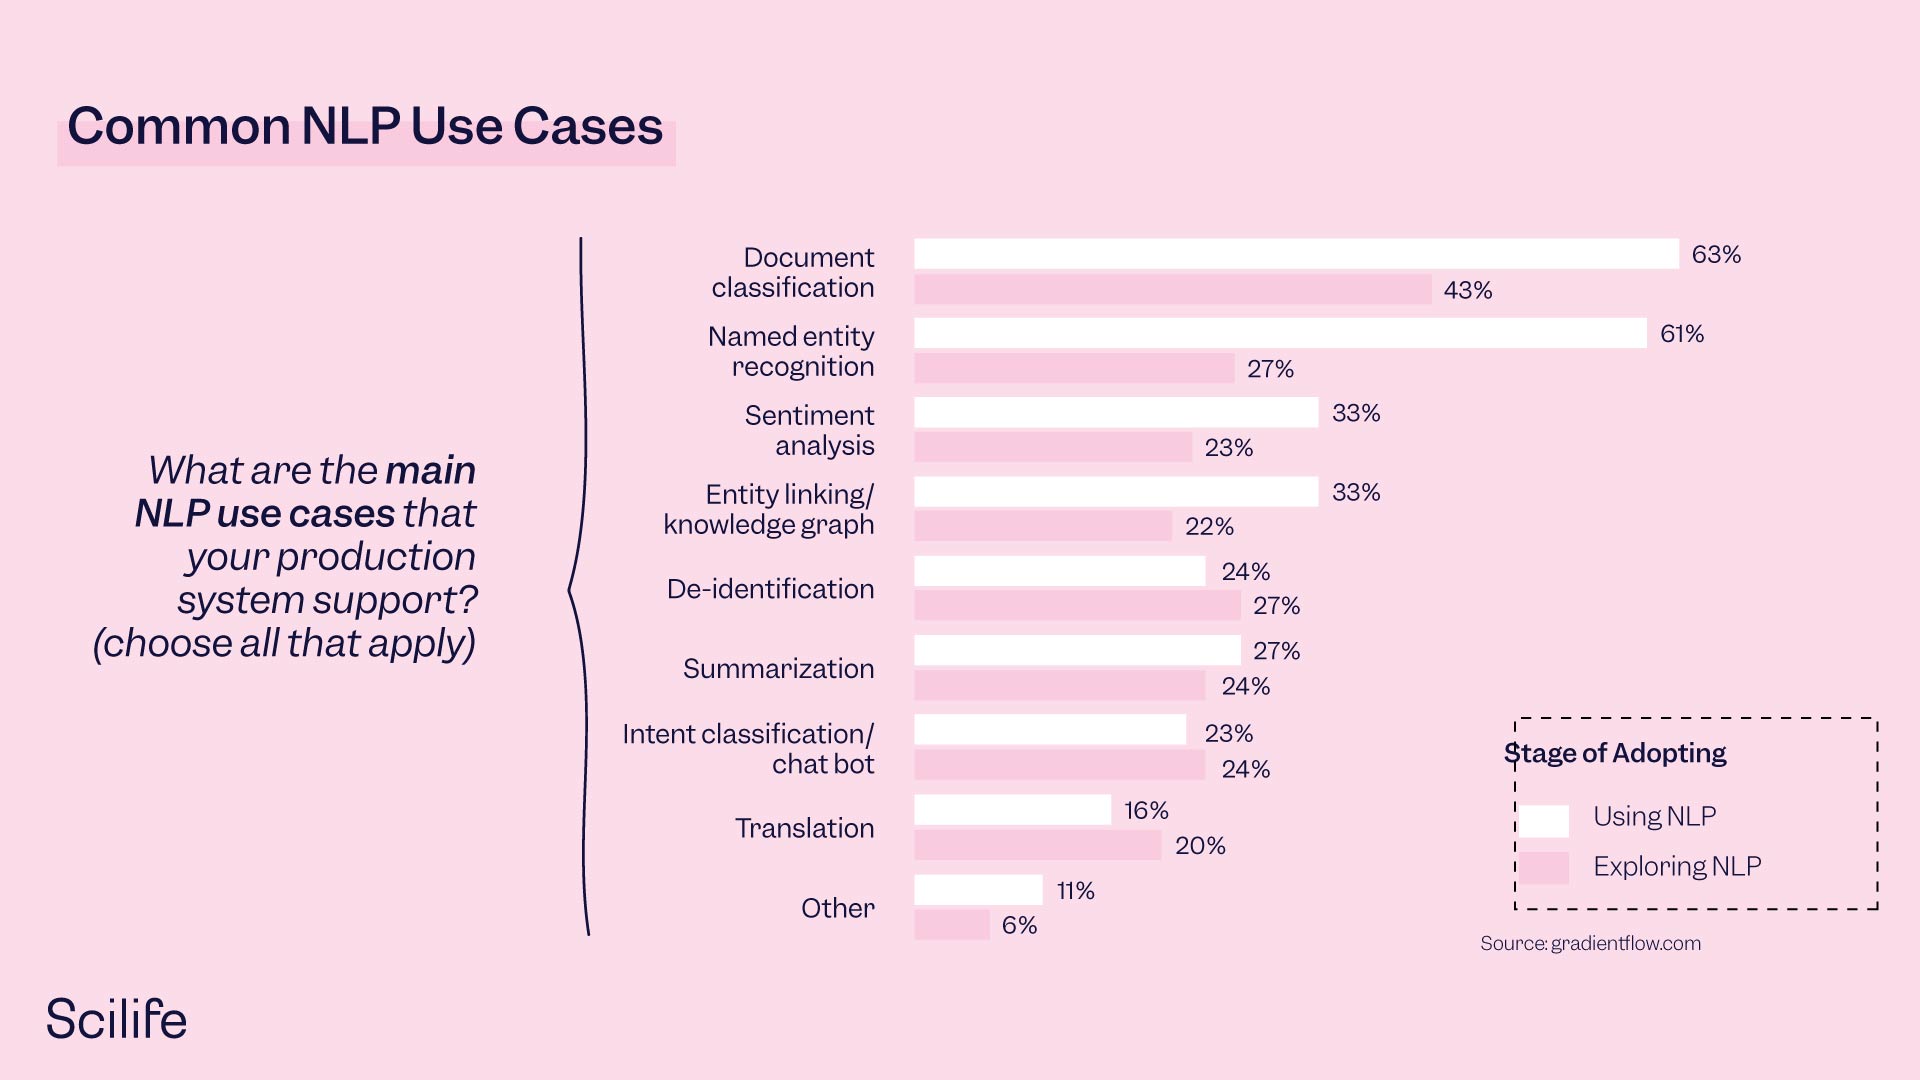
These examples illustrate some of the ways NLP and related AI technologies can process and interpret language. Common NLP use cases include:
- Document classification (text categorization): Assigning a document to one or more predefined categories.
- Online content moderation: Assessing online content, such as product reviews, to determine whether it is appropriate, relevant, or valid.
- Toxic content detection: Automatically identifying hate speech, obscene language, or threats on social media.
- Named entity recognition: Finding drugs, doses, adverse events, batch numbers, or dates in free text.
- Summarization: Condensing long documents, such as literature or deviation reports, for a person to review.
When selecting an NLP solution, organizations should consider factors such as accuracy, production readiness, processing speed, compatibility with their existing software stack, and scalability. It's also important to recognize that AI models are not perfect. Designing a product on the assumption that they will always produce accurate results is not advisable, and human oversight and feedback loops are essential for monitoring performance, identifying errors, and continuously improving the system.
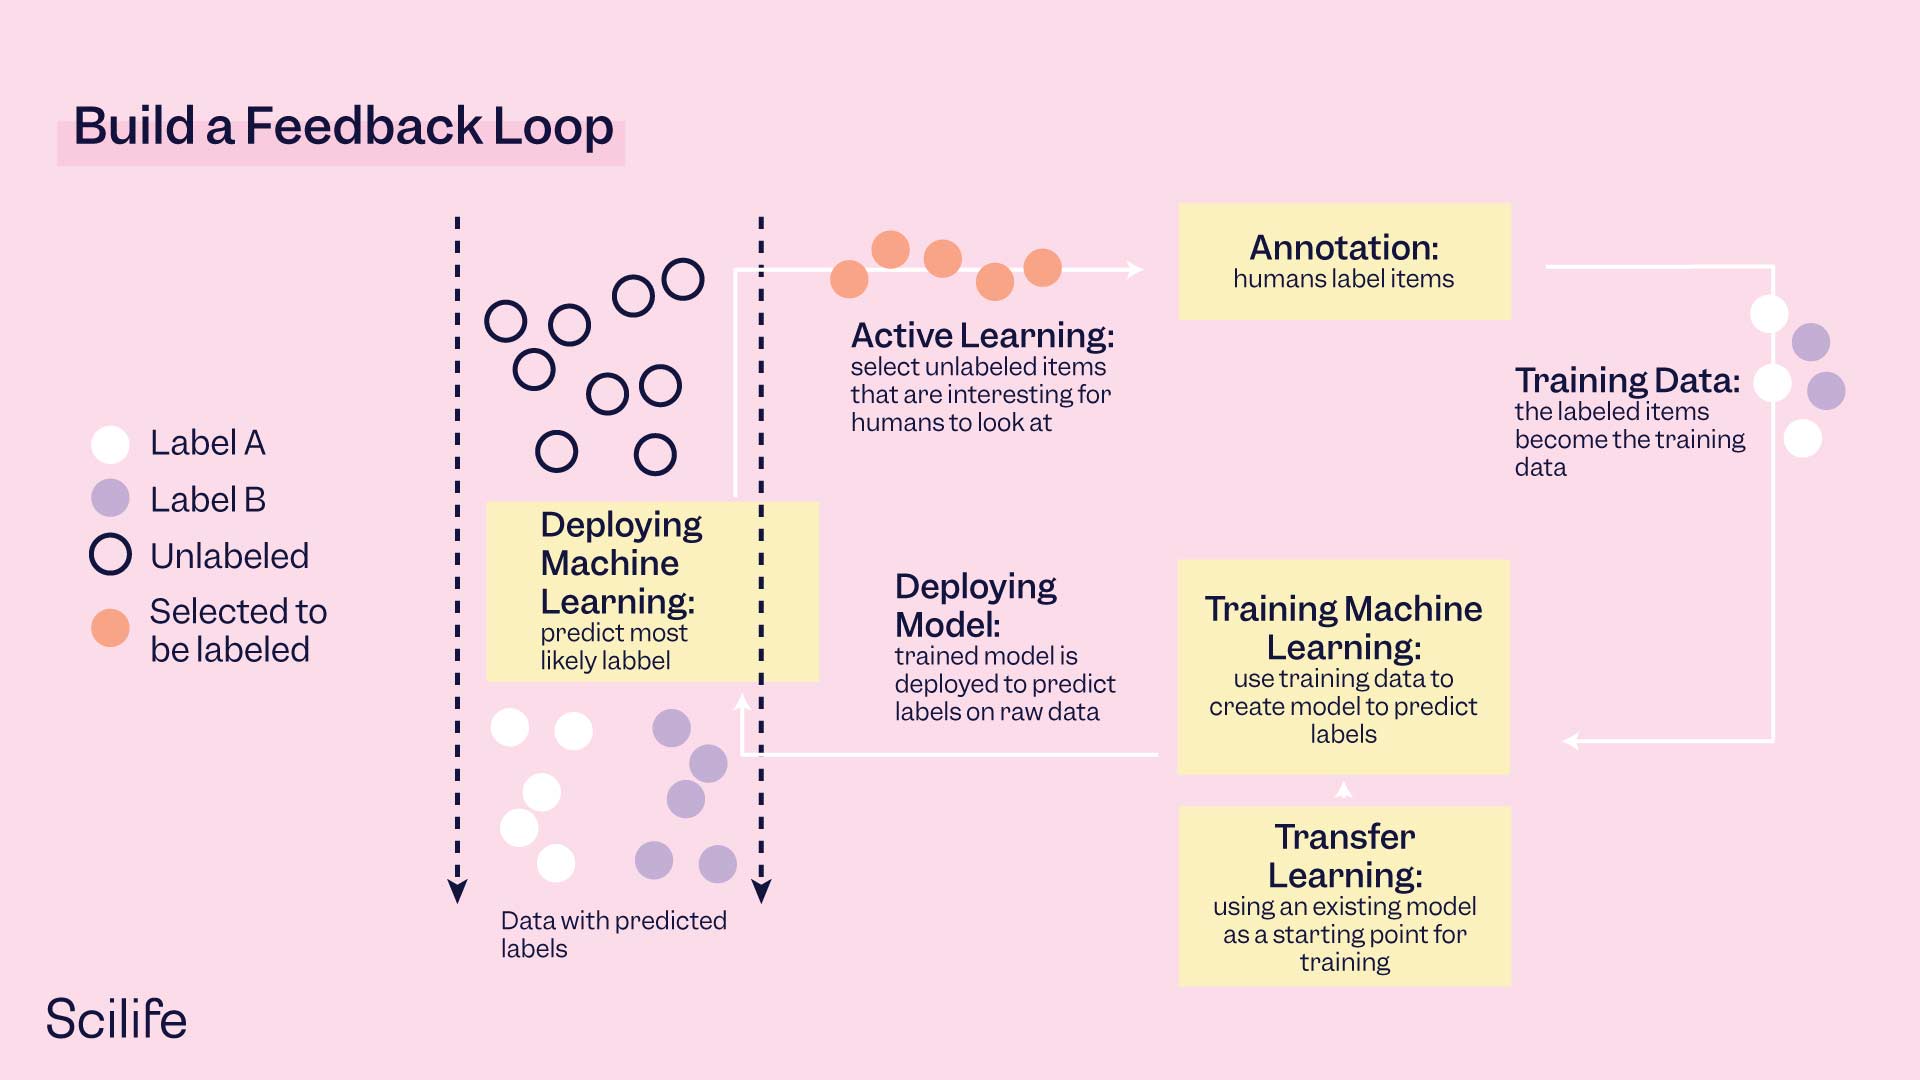
Although many open-source, pre-trained models and code resources already exist for common NLP applications, models can also be fine-tuned to meet specific requirements. Each retrained or fine-tuned version changes a validated system, so it must go through change control and be retested before release.
Creating, updating, and querying a biomedical knowledge graph
The pharmaceutical industry generates and works with vast amounts of unstructured data. In life sciences, researchers have estimated that, based on the volume of new research published each day, physicians would need to read clinical studies for 29 hours every workday to keep up with the latest advances. Clearly, this is not practical, and this is where biomedical knowledge graphs can help.
These knowledge graphs represent connections between different entities and their relationships, helping consolidate and organize complex information. Rather than manually reviewing countless studies, physicians can use NLP to extract and interpret information from biomedical knowledge graphs.
How to create a knowledge graph
Building a biomedical knowledge graph involves several steps, from collecting and structuring data to identifying relationships and generating meaningful insights.
- Data collection and ingestion: Public datasets and other relevant sources are combined to make information structured and accessible.
- Entity and relation extraction: NLP models identify relevant entities and the relationships between them, helping transform unstructured information into structured data.
- Graph connections: The model connects individual facts to create a knowledge graph, using techniques such as link prediction and node classification to identify relationships and patterns.
- Customized analytics and tool discovery: The model can support different organizational roles by tailoring insights and analytics to specific needs and helping users explore the underlying domain.
Biomedical knowledge graphs are therefore valuable tools for representing complex biomedical concepts and the relationships between them.
Migrating clinical trial documents to the trial master file (TMF)
Good Clinical Practice requires a complete, inspection-ready trial master file (TMF) for every trial. A migration puts that at risk if documents are misfiled or lose their metadata.
When a company acquires another organization, drug, or IT system, the associated TMF documentation often needs to be migrated to align with the acquiring company's standards. However, there is no direct one-to-one mapping between different TMF standards. As a result, tens or even hundreds of thousands of documents may need to be classified, with their associated metadata extracted and mapped correctly.
Traditional document migration processes can be slow and inconsistent. AI-assisted migration tools, by contrast, can make the process faster and more efficient.
This is because AI-enabled migration tools can:
- Extract information based on the training data.
- Classify documents and extract the most relevant information.
- Read scanned and handwritten documents with optical character recognition (OCR) and handwriting recognition.
Additional capabilities include language detection and support for both real-time and batch processing. Together, these features can help reduce the time, effort, and cost involved in TMF migration.
How can NLP improve adverse drug event (ADE) detection and reporting?
Let's look at adverse event detection and pharmacovigilance. Although medicines and vaccines undergo rigorous testing for safety and efficacy during clinical trials, some adverse effects may only become apparent once these products are used by larger, more diverse patient populations in real-world settings, including people with other concurrent conditions.
Detecting and reporting adverse drug events (ADEs) can present several challenges:
- A systematic review of 37 studies found a median under-reporting rate of 94% for adverse drug reactions.
- Manual case intake and triage are slow and hard to scale
- Siloed systems inhibit data capture and reporting.
- Data may be shared through nontraditional channels (e.g., social media).
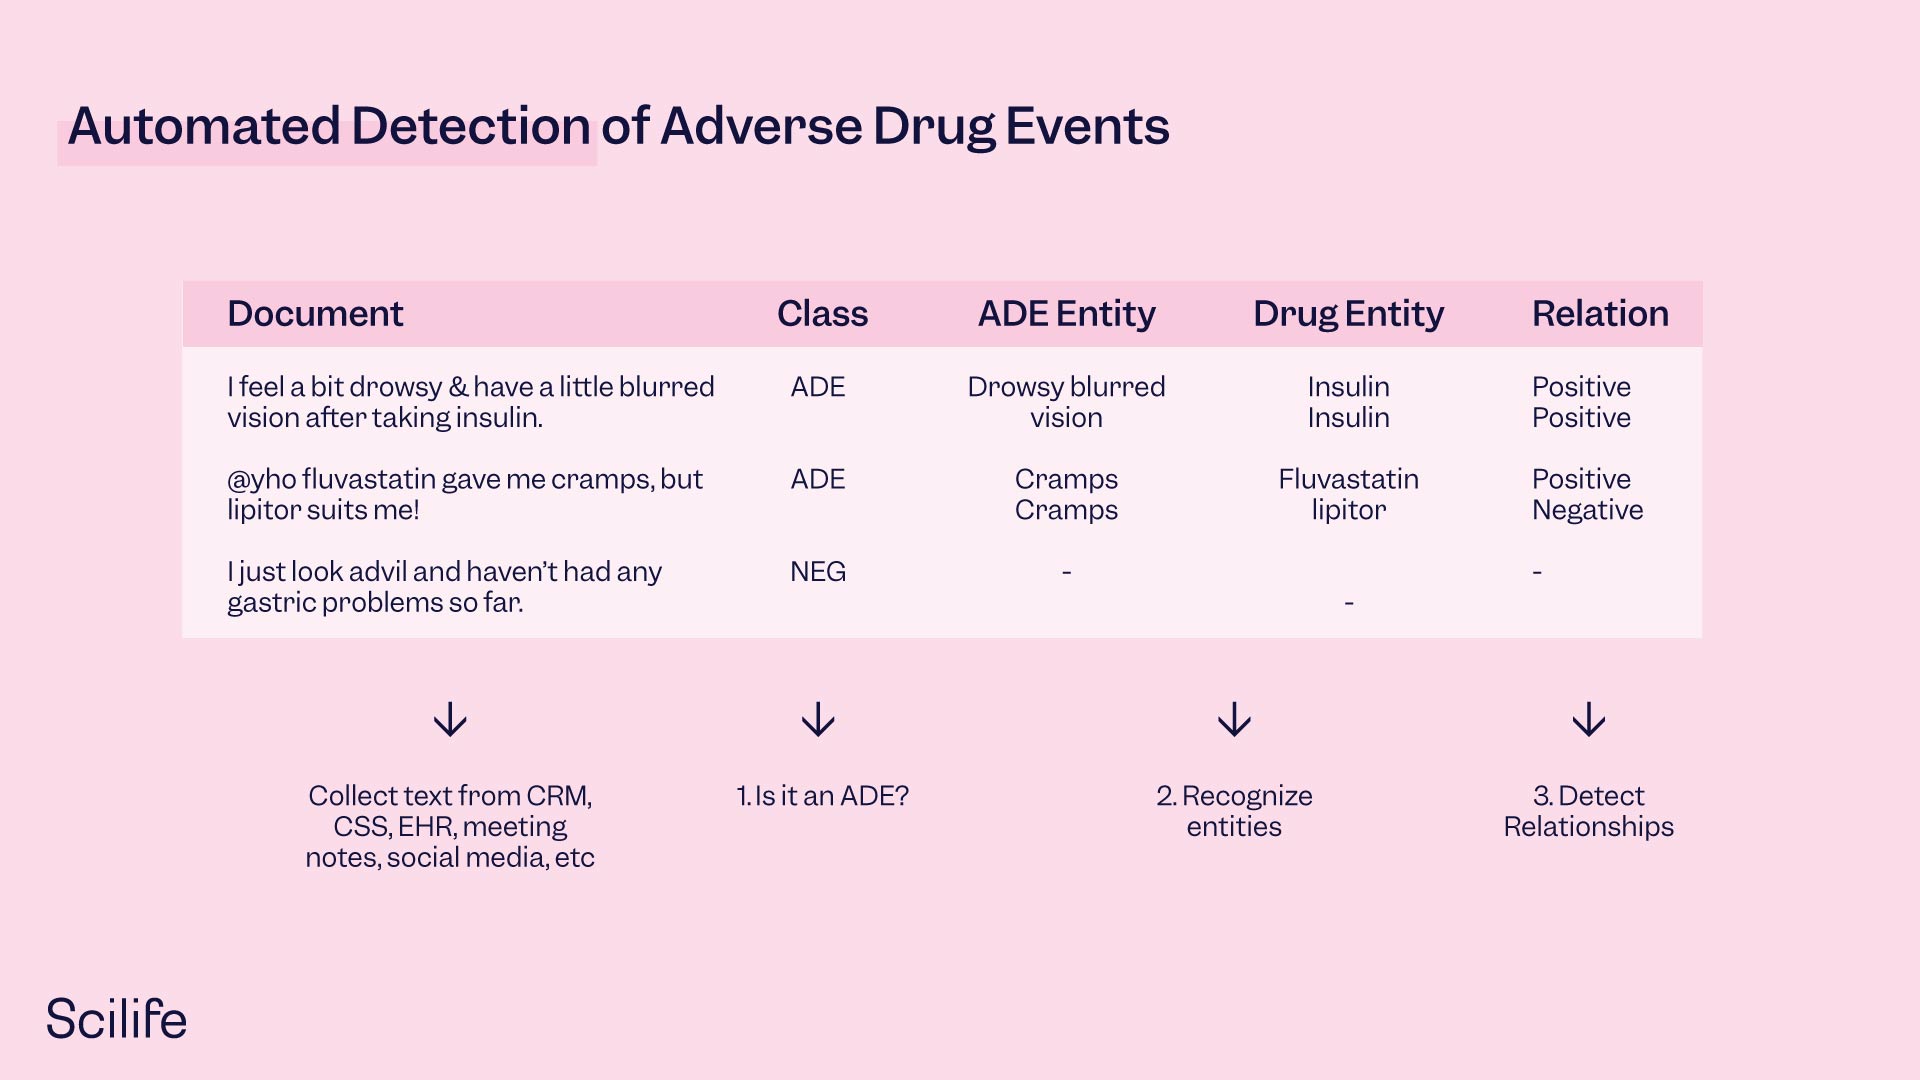
Automated ADE detection can help your organization strengthen its reporting. Pre-trained NLP models and pipelines can detect ADEs at scale, in many different languages, and ultimately increase the user’s reporting rate.
How fast is the NLP in the healthcare and life sciences market growing?
Clearly, demand for natural language processing keeps growing. MarketsandMarkets estimates the NLP in healthcare and life sciences market was valued at:
- USD 4.13 billion in 2024
- USD 5.18 billion in 2025
- USD 16.01 billion by 2030, a compound annual growth rate (CAGR) of 25.3% from 2025 to 2030
This projected growth reflects the increasing role of NLP in healthcare and life sciences, where organizations can use the technology to process large volumes of information and support more efficient workflows.
However, adoption in regulated life sciences contexts also brings regulatory considerations. NLP and other AI systems may fall under the EU AI Act, depending on their intended purpose and classification. Following the Digital Omnibus on AI (Regulation (EU) 2026/1744), the application dates for high-risk AI obligations are December 2, 2027 for systems covered by Annex III and August 2, 2028 for AI systems that are safety components of, or are themselves, products covered by EU harmonization legislation and need third-party conformity assessment, such as medical devices.
For most life sciences teams, NLP used for literature review, TMF management, or case intake is unlikely to be high-risk under the AI Act. These uses don’t appear in Annex III, and the system usually isn’t a safety component of a product covered by Annex I legislation, such as the MDR. Two sets of obligations still apply.
First, AI literacy: Article 4 has applied since February 2, 2025. As amended by Regulation (EU) 2026/1744, it requires providers and deployers to take measures to support the AI literacy of staff who operate or use AI systems.
Second, GxP: whatever the system’s AI Act classification, you must validate it for its intended use, under EU GMP Annex 11 or EMA’s Guideline on computerized systems and electronic data in clinical trials. For NLP in GMP processes, also look to draft Annex 22. Its 2025 consultation version excludes generative AI and LLMs from critical GMP applications.
Conclusion
From organizing trial documents to identifying potential adverse drug events, NLP can help pharma teams turn complex information into useful insights. Getting value from these tools requires reliable data, appropriate validation, and human oversight, supported by strong quality processes.
A connected quality management system provides a foundation for managing the documents, training, and processes that support consistent, compliant operations.